What is the Null Hypothesis and Its Importance in Research?
The null hypothesis is not a claim anyone believes. It is a reference point: the assumption a test computes its numbers under. Almost every serious misreading of a result — above all, treating a non-significant finding as proof of no effect — comes from losing sight of that one fact.
- What a p-value measures, quoted from the American Statistical Association’s own definition
- What type I and type II errors, alpha, beta and power each refer to, and what they do not
- What to do when the finding you actually want to report is that there is no meaningful difference
- “p > 0.05 means there is no effect, and p is the probability the null hypothesis is true.” Both are false, and both are on the published list of common misinterpretations. The p-value “assumes the test hypothesis is true — it is not a hypothesis probability”,2 and it is “a mistake to conclude from P > 0.05 that a study found ‘no association’”.2
What the null hypothesis is
A statistical test needs something to compute against. The null hypothesis supplies it: a specified state of affairs, usually “no effect” or “no difference”, under which the behaviour of the data can be worked out mathematically. In the standard formulation, “the targeted effect size is a ‘null’ value representing zero effect”, and “the test hypothesis is called the null hypothesis”.2
Two features follow from that, and both are routinely forgotten.
First, the null is an assumption made for the purpose of calculation, not a belief. Nobody is required to think it is true. It is held fixed so that the probability of various results can be computed, and the observed result compared against them.
Second, a test never evaluates the null in isolation. It evaluates the data against a whole statistical model, of which the null is one component. The American Statistical Association’s statement on p-values is careful about this: a p-value “can indicate how incompatible the data are with a specified statistical model”, and that model includes every assumption made, not just the null.1
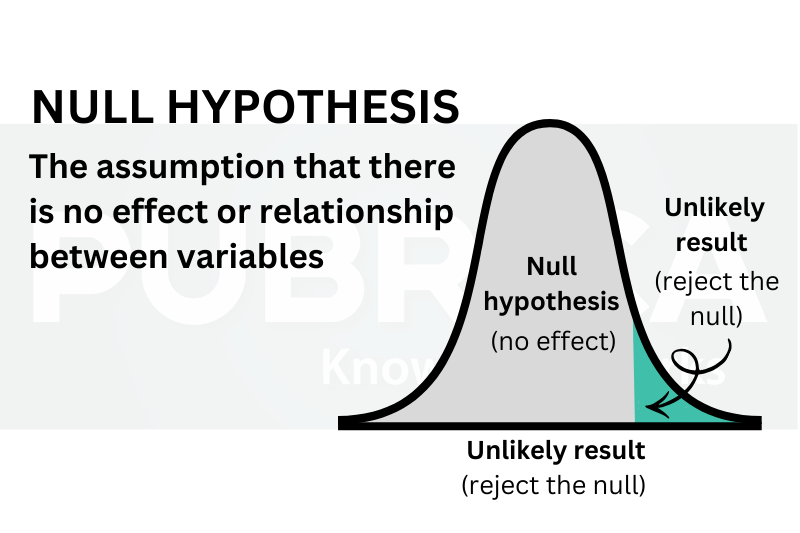
Null and alternative, side by side
| Feature | Null hypothesis (H0) | Alternative hypothesis (H1) |
|---|---|---|
| What it states | No effect, no difference, or no association in the population | An effect, difference or association exists |
| Its role in the test | The assumption the calculation is performed under2 | The direction the evidence may point, if the null is rejected |
| What the data can do to it | It can be rejected, or not rejected. It is never proved2 | It is supported indirectly, by the null being rejected |
| Error attached to it | Rejecting it wrongly is a type I error, probability alpha4 | Failing to detect it is a type II error, probability beta4 |
| Worked example | The new analgesic and placebo produce the same mean pain score | The new analgesic produces a different mean pain score |
The awkward wording carries real content. A test can find the data incompatible with the null, which licenses rejection. It cannot find the data compatible enough to establish the null, because many other values are also compatible with the same data. That is why Altman and Bland insist on the distinction between a study showing “that there is no difference” and one showing “an absence of evidence of a difference”, adding that “these are quite different statements”.3
What a p-value actually measures
The ASA gives the definition in one sentence: “informally, a p-value is the probability under a specified statistical model that a statistical summary of the data … would be equal to or more extreme than its observed value”.1 Greenland and colleagues phrase it as “the probability that the chosen test statistic would have been at least as large as its observed value”, computed under the test hypothesis.2
Read either definition slowly and two things stand out. The probability is of data, not of a hypothesis, and it is computed assuming the null is true.
The six principles
The ASA statement sets out six principles. They are short, and worth reading in full rather than in summary.1
| # | Principle, verbatim |
|---|---|
| 1 | “P-values can indicate how incompatible the data are with a specified statistical model.”1 |
| 2 | “P-values do not measure the probability that the studied hypothesis is true, or the probability that the data were produced by random chance alone.”1 |
| 3 | “Scientific conclusions and business or policy decisions should not be based only on whether a p-value passes a specific threshold.”1 |
| 4 | “Proper inference requires full reporting and transparency.”1 |
| 5 | “A p-value, or statistical significance, does not measure the size of an effect or the importance of a result.”1 |
| 6 | “By itself, a p-value does not provide a good measure of evidence regarding a model or hypothesis.”1 |
Principle 2 is the one that disposes of the most common error in research writing. A p-value of 0.03 does not mean a 3% chance the null is true, and it does not mean a 97% chance the finding is real. Greenland and colleagues list that reading first among their misinterpretations and label it false: “the P value assumes the test hypothesis is true — it is not a hypothesis probability”.2
Principle 6 adds a quieter point with large consequences: “a p-value near 0.05 taken by itself offers only weak evidence against the null hypothesis”.1 The conventional threshold is not a bright line between established and unestablished.
Type I error, type II error and power
Because the test can be wrong in two directions, two error rates are defined. Perezgonzalez states them cleanly: “a Type I error … is made every time the main hypothesis is wrongly rejected”, and “a Type II error … is made every time the main hypothesis is wrongly retained”.4 The attached probabilities are long-run rates: “alpha is the probability of committing a Type I error in the long run”, and “beta is the probability of committing a Type II error in the long run”.4
Power is the complement of beta. It “is the probability of correctly rejecting the main hypothesis in favour of the alternative hypothesis”, and is “the mathematical opposite of the Type II error (thus, 1−β)”.4 Greenland and colleagues define it as “the pre-study probability that the test will reject the test hypothesis” when a given alternative holds.2 Because power is a property of the design, a study built without a credible comparison — as in a pre-experimental design — cannot recover it at the analysis stage.
| Quantity | What it is | Set by |
|---|---|---|
| Alpha (α) | The probability of rejecting a true null6 | The researcher, in advance. “The cut-off value α is supposed to be fixed in advance and is thus part of the study design, unchanged in light of the data”2 |
| Beta (β) | The probability of failing to reject a false null6 | Follows from alpha, effect size and sample size |
| Power (1 − β) | The probability of detecting a real effect of a given size4 | Design. “The ideal power of a study is considered to be 0.8”6 |
| Sample size | The lever that moves power5 | “Increasing sample size increases power”4 |
Jones, Carley and Harrison put the planning consequence directly: “power calculations tell us how many patients are required in order to avoid a type I or a type II error”.5 The common reason for a type II error is simply too few participants — “the most common reason for this type of error is small sample size”6 — and both small samples and small effects erode power: “both small sample sizes and low effect sizes reduce the power in the study”.6
If a study had little chance of detecting the effect it was looking for, a non-significant result tells you almost nothing. Greenland and colleagues make the point in one image: “especially when a study is small, even large effects may be drowned in noise”.2 This is why power belongs in the protocol, not in the discussion section as an excuse.
Figures: hypothesis testing explained
Figure 1 sets out the four possible outcomes of a statistical test and the error rates associated with them. Figure 2 shows what a p-value measures under the null hypothesis. Together they help authors report and interpret test results without the common misreadings that reviewers flag.
Two states of the world, two decisions. Alpha and beta are the probabilities of the two mistakes, fixed before the data arrive.
What to look for. A type I error “is made every time the main hypothesis is wrongly rejected”; a type II error “is made every time the main hypothesis is wrongly retained”.4 Alpha and beta are long-run probabilities of those mistakes, and power “is the probability of correctly rejecting the main hypothesis in favour of the alternative hypothesis”, which is “the mathematical opposite of the Type II error (thus, 1−β)”.4 None of the four cells is the probability that the null is true.
Schematic representation of the decision structure, not data.
The curve is the distribution of the test statistic assuming the null is true. The shaded tails are the p-value.
What to look for. The American Statistical Association defines it precisely: “informally, a p-value is the probability under a specified statistical model that a statistical summary of the data … would be equal to or more extreme than its observed value”.1 Everything on this diagram is drawn on the assumption that the null is true. That is why, as Greenland and colleagues put it, “the P value assumes the test hypothesis is true — it is not a hypothesis probability”.2
Schematic. The curve is illustrative and plots no dataset.
Where 0.05 came from
The threshold is a convention with a traceable history, not a property of nature. Trkulja and Hrabač give the short answer: “the common (and basically correct) answer is that this ‘critical’ P-value was determined arbitrarily, but with a reason”.7
They trace the concept of statistical significance to Edgeworth in 1885, note that “the term itself was adopted by Fisher, who added the concept of null hypothesis”, and give the arithmetic behind the number: in his 1925 work Fisher “defined more precisely that the total area under the curve of the standard normal distribution that is below and above the mean ±3γ was 4.56%, which he rounded to 5%. And thus 0.05”.7
Fisher himself did not treat it as a fixed rule. Quoted by Lehmann, he wrote that “no scientific worker has a fixed level of significance at which from year to year, and in all circumstances, he rejects hypotheses; he rather gives his mind to each particular case in the light of his evidence and his ideas”.8 The step of fixing the threshold in advance came later, from Neyman and Pearson.7
Others state the arbitrariness plainly. Du Prel and colleagues note that “the definition of a significance limit is arbitrary”, and draw the practical conclusion: “there is little difference between the evidence for p-values of 0.04 and of 0.06”.9
Two frameworks fused into one
Part of the difficulty with the null hypothesis is that the procedure taught today is a blend of two different systems that were developed in opposition to each other.
Perezgonzalez describes the result bluntly: “NHST is, in reality, an amalgamation of Fisher’s and Neyman-Pearson’s theories, offered as a seamless approach to testing”, and “most amalgamations follow Neyman-Pearson procedurally but Fisher philosophically”.4 On his reading the two “are incompatible in most accounts”.4
Hubbard and Bayarri identify the specific casualty: “p’s and α’s are not the same thing; they measure different concepts”, and the “widespread failure to appreciate the incompatibility of Fisher’s evidential p value” with Neyman-Pearson error rates has consequences, because “the misinterpretation of p values results in an overstatement of the evidence against the null hypothesis”.10
This page would misrepresent the literature if it presented incompatibility as settled. Lehmann, reviewing the dispute, concluded that “despite basic philosophical differences, in their main practical aspects the two theories are complementary rather than contradictory”, and that “the ferocity of the rhetoric has created an exaggerated impression of irreconcilability”.8 What is not disputed is the practical advice that follows either way: do not read a p-value as a type I error rate.410
Why the null hypothesis matters
Four things depend on having stated one.
- It makes the calculation possible. Without a specified state to compute under, there is no distribution against which to judge the observed result, and therefore no p-value. This is why the hypothesis belongs to the experimental design rather than to the analysis.1
- It supplies a neutral starting point. The analysis begins from the position that the hoped-for effect is absent, so the data have to argue for it rather than against a position already favoured.
- It fixes the error you are willing to tolerate. Alpha is set in advance and is part of the design, “unchanged in light of the data”.2 Setting it afterwards is not an analysis choice; it is a way of guaranteeing the answer.
- It makes the study auditable. A stated hypothesis can be checked against what was actually tested. An unstated one cannot.16
The mistake that matters most
Of all the errors in this area, one does the most damage: reading a non-significant result as evidence that there is no effect.
Greenland and colleagues list it twice over. Misinterpretation 4: “a nonsignificant test result (P > 0.05) means that the test hypothesis is true or should be accepted” — false. Misinterpretation 6: “a null-hypothesis P value greater than 0.05 means that no effect was observed” — also false.2 They add that it is “a mistake to conclude from P > 0.05 that a study found ‘no association’” unless the point estimate happens to sit exactly on the null value.2
Altman and Bland had made the same point two decades earlier, in the article whose title has become the standard shorthand. Calling a trial “negative”, they wrote, “wrongly implies that the study has shown that there is no difference, whereas usually all that has been shown is an absence of evidence of a difference”.3
The remedy both papers recommend is to stop reporting whether a threshold was crossed and start reporting how large the effect might be. Altman and Bland advise that “we should look for quantification of the association rather than just a P value”,3 and note that low power produces “a wide confidence interval for the treatment difference”3 — which is itself the honest signal that the study could not settle the question. Du Prel and colleagues explain why the interval carries more: “p-values alone do not permit any direct statement about the direction or size of a difference”.9 Gardner and Altman argued for this shift as early as 1986, on the grounds that “investigators are usually interested in determining the size of difference of a measured outcome between groups, rather than a simple indication of whether or not it is statistically significant”.11
Showing there is no meaningful difference
Sometimes the finding you want really is that two things are equivalent — that a cheaper treatment works as well, or that a change did no harm. A non-significant result cannot establish that. A different test can.
Lakens states the problem and the remedy together: “scientists should be able to provide support for the absence of a meaningful effect”, yet “currently researchers often incorrectly conclude an effect is absent based on a non-significant result”, when in fact “it is not possible to conclude there is no effect when p > α”.12
The standard tool is equivalence testing. “A very simple equivalence testing approach is the ‘two-one-sided t-tests’ (TOST) procedure”, which “entails performing two one-sided tests to examine whether the observed data is surprisingly larger than a lower equivalence boundary”, and smaller than an upper one.12 The boundaries are the smallest effect size of interest — set, crucially, before the data are seen.12
In clinical research the same logic appears as non-inferiority testing. Pinto describes the underlying error precisely: “the non-significance in a traditional test does not support the conclusion of absence of difference”, which is why non-inferiority trials exist as “experimental models designed to determine whether a new treatment or procedure is not less effective than an established one”.13 The margin “quantifies the maximal loss of clinically acceptable efficacy” and “must be defined prior to the study”.13
Ahn and colleagues add the mechanics: such testing “generally uses a confidence interval”, with equivalence claimed when the interval falls within the predetermined margin — a margin that “should be justified both clinically and statistically” and “be chosen conservatively to avoid making a false claim of equivalence/noninferiority for an inferior outcome”.14
One-sided or two-sided
A two-sided test asks whether the effect differs from the null in either direction. A one-sided test asks about one direction only, and buys power by giving up the ability to detect the other.
The guidance is consistent and strict. Bland and Altman: “one sided tests are not often used, and sometimes they are not justified”; “expectation of a difference in a particular direction is not adequate justification”; and most pointedly, “one sided tests should never be used simply as a device to make a conventionally non-significant difference significant”. Their conclusion: “two sided tests should be used unless there is a very good reason for doing otherwise”, and “if one sided tests are to be used the direction of the test must be specified in advance”.15
Lydersen reaches the same place and names the exception: a one-sided test is defensible “only if an effect in the opposite direction is impossible or of no interest”, and “the only important exception is non-inferiority trials, where it is appropriate to use one-sided tests”.16 The rule about declaring the direction in advance, he notes, “seems to have been frequently disregarded”.16
Stating the hypothesis in advance
A null hypothesis chosen after the results are known is not performing the function described above. The practice has a name — HARKing, hypothesising after the results are known — defined by Kerr as “presenting a post hoc hypothesis in the … report as if it were an a priori hypothesis”.18
Nosek and colleagues explain why it corrupts the p-value specifically: “the diagnosticity of a p-value is contingent on knowing how many tests were performed”, so undisclosed flexibility “leaves the observed p-values with unknown diagnosticity rendering them uninterpretable”.17 The remedy they propose is not to forbid exploration but to label it: preregistration “can establish a bright line between prediction and postdiction”, and “does not favor prediction over postdiction; its purpose is to make clear which is which”.17 It “does not eliminate the possibility of poor statistical practices, but it does make them detectable”.17
Murphy and Aguinis quantify the direction of the damage: HARKing “should lead to a bias toward statistically significant as well as large rather than” small reported effects.19 Munafò and colleagues place it among the practices preregistration addresses, alongside outcome switching and p-hacking.20
When you may not need one
Not all research tests hypotheses, and a null hypothesis forced onto a study that is not testing anything adds nothing.
- Exploratory and qualitative work. Research designed to generate hypotheses rather than test them has nothing to specify in advance. Stating a null afterwards to make the write-up look confirmatory is precisely the practice described in the previous section.18
- Purely descriptive analysis. Reporting what a population looks like — prevalence, distribution, characteristics — is estimation, not testing. The appropriate output is an estimate with an interval. The same applies to a correlational study reported as a coefficient with its interval.9
- Estimation-first approaches. Where the question is how large an effect is rather than whether it differs from zero, confidence intervals answer it directly and the null plays no part.112
- Equivalence questions. As above, these need their own test and their own pre-specified margin, not a conventional null.12
The wider reform debate goes further. The ASA’s third principle already says decisions “should not be based only on whether a p-value passes a specific threshold”.1 Amrhein, Greenland and McShane went on to call, with more than 800 co-signatories, for “an end to hyped claims and the dismissal of possibly crucial effects”.21 None of that makes the null hypothesis useless. It makes the threshold ritual around it the thing to drop.
Common mistakes
| Mistake | Stage | What it costs | What to do instead |
|---|---|---|---|
| Reading p > 0.05 as “no effect” | Interpretation | The most consequential error in the field; listed twice among published misinterpretations2 | Report the estimate and its interval, and say the study did not settle the question3 |
| Reading p as the probability the null is true | Interpretation | Contradicts the definition: the p-value assumes the null2 | Hold on to principle 2 of the ASA statement1 |
| Treating p as a measure of effect size | Interpretation | “A p-value … does not measure the size of an effect or the importance of a result”1 | Report the effect size separately, with an interval9 |
| Switching to a one-sided test after seeing p = 0.08 | Analysis | “One sided tests should never be used simply as a device to make a conventionally non-significant difference significant”15 | Specify the direction in advance, or use a two-sided test15 |
| Choosing alpha after seeing the result | Analysis | Alpha is “part of the study design, unchanged in light of the data”2 | Fix it in the protocol4 |
| Claiming equivalence from a non-significant test | Interpretation | “It is not possible to conclude there is no effect when p > α”12 | Run an equivalence or non-inferiority test with a pre-set margin13 |
| Presenting a post hoc hypothesis as pre-specified | Write-up | Renders the p-value uninterpretable, since the number of tests is unknown17 | Preregister, and label exploratory findings as exploratory17 |
| Reporting significance from an underpowered study | Design | Small studies let even large effects be “drowned in noise”2 | Calculate power in advance; 0.8 is the usual floor6 |
| Treating 0.05 as a boundary of fact | Interpretation | “There is little difference between the evidence for p-values of 0.04 and of 0.06”9 | Report the exact value and interpret it alongside the interval and the design1 |
| Mistaking a p-value for a type I error rate | Interpretation | They “measure different concepts”, and conflating them overstates the evidence10 | Keep the Fisher and Neyman-Pearson quantities distinct4 |
Take-home message
The null hypothesis is the assumption a test computes under, not a belief anyone holds. The p-value it produces is the probability of data at least as extreme as yours if that assumption is true — never the probability that the assumption is true, and never a measure of how large an effect is. A result above the threshold means the study did not find evidence of a difference, not that there is none. If the absence of a meaningful difference is the finding you want, equivalence or non-inferiority testing is the tool, with a margin set in advance. State the hypothesis, the direction and the alpha before the data arrive, and report the interval rather than the verdict.
How to apply this to your work
- Write the null and the alternative out in full before collecting data, in terms of the population parameter rather than the sample.2
- Fix alpha in the protocol, and do not revise it once results are in.2
- Calculate power and the required sample size in advance, taking 0.8 as the usual floor.6
- Use a two-sided test unless there is a very good reason, declared beforehand, to do otherwise.15
- Report the exact p-value, the effect size and the confidence interval — not just whether a threshold was crossed.19
- If you want to show equivalence, test for it, with a margin justified clinically and statistically and set in advance.14
- Preregister the analysis plan, so exploratory findings can be labelled as such rather than disguised.17
- Phrase a non-significant result accurately: the study found no evidence of a difference, which is not the same as evidence of no difference.3
Common questions
What is the null hypothesis in simple terms?
It is the assumption that there is no effect, no difference or no association — stated so that a test has something to calculate against. In the standard formulation “the targeted effect size is a ‘null’ value representing zero effect”.2 It is a reference point for the arithmetic, not a belief about the world.
Does a p-value tell you the probability that the null hypothesis is true?
No. This is the most common error about p-values, and the American Statistical Association addresses it directly: “p-values do not measure the probability that the studied hypothesis is true, or the probability that the data were produced by random chance alone”.1 The p-value is computed assuming the null is true, so it cannot also be the probability that it is.2
Does p > 0.05 mean there is no effect?
No. It means the data were not sufficiently incompatible with the null, at the chosen threshold. Greenland and colleagues list “a null-hypothesis P value greater than 0.05 means that no effect was observed” among the misinterpretations, and note it is a mistake to conclude from P > 0.05 that a study found “no association”.2 In Altman and Bland’s phrase, absence of evidence is not evidence of absence.3
Why can you never prove the null hypothesis?
Because the data compatible with “no difference” are also compatible with many small differences. A test can show incompatibility, which licenses rejection; it cannot show that one particular value among many is the true one. If the absence of a meaningful difference is what you need to establish, equivalence testing is the appropriate tool.12
What is the difference between a type I and a type II error?
A type I error “is made every time the main hypothesis is wrongly rejected” — a false positive, with probability alpha. A type II error “is made every time the main hypothesis is wrongly retained” — a false negative, with probability beta.4 Power, the probability of detecting a real effect, is 1 − beta.4
Why is 0.05 the usual threshold?
By convention, traceable to Fisher. In his 1925 work he noted that the area beyond roughly three standard deviations either side of the mean “was 4.56%, which he rounded to 5%. And thus 0.05”.7 The cut-off “was determined arbitrarily, but with a reason”,7 and “there is little difference between the evidence for p-values of 0.04 and of 0.06”.9
Should I use a one-sided or a two-sided test?
Two-sided, in almost all cases. “Two sided tests should be used unless there is a very good reason for doing otherwise”, and expecting a difference in a particular direction “is not adequate justification”.15 The clear exception is non-inferiority testing.16 If a one-sided test is used, the direction must be specified in advance.15
Does every study need a null hypothesis?
No. Exploratory, qualitative and purely descriptive work tests nothing, and estimation-first analyses answer “how large” rather than “is it zero”. What matters is not forcing a null onto such a study afterwards so the write-up looks confirmatory — that is hypothesising after the results are known.1817
Declared interest: Pubrica provides statistical analysis and manuscript support commercially. Nothing on this page should be read as suggesting that any analysis service can make a non-significant result support a claim of no effect; that is a property of the design and the question, not of the analyst.
References and sources
- Wasserstein RL, Lazar NA. The ASA’s statement on p-values: context, process, and purpose. The American Statistician. 2016;70(2):129–133. doi:10.1080/00031305.2016.1154108 read 20 October 2026 from a university-hosted copy of the published article.View the full text
- Greenland S, Senn SJ, Rothman KJ, Carlin JB, Poole C, Goodman SN, Altman DG. Statistical tests, P values, confidence intervals, and power: a guide to misinterpretations. European Journal of Epidemiology. 2016;31:337–350. doi:10.1007/s10654-016-0149-3 read 20 October 2026.View the version of record
- Altman DG, Bland JM. Statistics notes: absence of evidence is not evidence of absence. BMJ. 1995;311(7003):485. doi:10.1136/bmj.311.7003.485 read 20 October 2026.View on the BMJ
- Perezgonzalez JD. Fisher, Neyman-Pearson or NHST? A tutorial for teaching data testing. Frontiers in Psychology. 2015;6:223. doi:10.3389/fpsyg.2015.00223 read 20 October 2026.View on Frontiers in Psychology
- Jones SR, Carley S, Harrison M. An introduction to power and sample size estimation. Emergency Medicine Journal. 2003;20:453–458. read 20 October 2026 from a university-hosted copy; no DOI was printed on the copy reached.View the article PDF
- Serdar CC, Cihan M, Yücel D, Serdar MA. Sample size, power and effect size revisited: simplified and practical approaches in pre-clinical, clinical and laboratory studies. Biochemia Medica. 2021;31(1):010502. doi:10.11613/BM.2021.010502 read 20 October 2026.View the full text
- Trkulja V, Hrabač P. Further thoughts on P. Croatian Medical Journal. 2019;60:570–573. doi:10.3325/cmj.2019.60.570 read 20 October 2026 from an institutional repository copy.View the full text
- Lehmann EL. The Fisher, Neyman-Pearson theories of testing hypotheses: one theory or two? Journal of the American Statistical Association. 1993;88(424):1242–1249. read 20 October 2026; no DOI was printed on the copy reached. The Fisher quotation is as given by Lehmann.View the article PDF
- du Prel J-B, Hommel G, Röhrig B, Blettner M. Confidence interval or p-value? Part 4 of a series on evaluation of scientific publications. Deutsches Ärzteblatt International. 2009;106(19):335–339. doi:10.3238/arztebl.2009.0335 read 20 October 2026 from a university-hosted copy.View the full text
- Hubbard R, Bayarri MJ. Confusion over measures of evidence (p’s) versus errors (α’s) in classical statistical testing. The American Statistician. 2003;57(3):171–178. read 20 October 2026; no DOI was printed on the copy reached.View the article PDF
- Gardner MJ, Altman DG. Confidence intervals rather than P values: estimation rather than hypothesis testing. British Medical Journal (Clinical Research Edition). 1986;292(6522):746. doi:10.1136/bmj.292.6522.746 abstract read 20 October 2026; the full text is paywalled, and the quotation here comes from the abstract.View on the BMJ
- Lakens D. Equivalence tests: a practical primer for t tests, correlations, and meta-analyses. Social Psychological and Personality Science. 2017;8(4):355–362. doi:10.1177/1948550617697177 the author’s accepted manuscript was read 20 October 2026; journal, volume and page details are from the published record rather than the document read.View the accepted manuscript
- Pinto VF. Non-inferiority clinical trials: concepts and issues. Jornal Vascular Brasileiro. 2010;9(3):145–151. doi:10.1590/S1677-54492010000300009 read 20 October 2026.View on SciELO
- Ahn S, Park SH, Lee KH. How to demonstrate similarity by using noninferiority and equivalence statistical testing in radiology research. Radiology. 2013;267(2):328–338. doi:10.1148/radiol.12120725 read 20 October 2026.View on Radiology
- Bland JM, Altman DG. Statistics notes: one and two sided tests of significance. BMJ. 1994;309(6949):248. doi:10.1136/bmj.309.6949.248 read 20 October 2026. The journal’s own page prints the second author’s surname incorrectly; the Statistics Notes series is by Bland and Altman.View on the BMJ
- Lydersen S. Why are one-sided hypothesis tests rarely used? Tidsskrift for Den norske legeforening. 2021;141. doi:10.4045/tidsskr.21.0111 read 20 October 2026.View the article
- Nosek BA, Ebersole CR, DeHaven AC, Mellor DT. The preregistration revolution. Proceedings of the National Academy of Sciences. 2018;115(11):2600–2606. doi:10.1073/pnas.1708274114 the accepted manuscript was read 20 October 2026; journal, volume and page details are from the published record rather than the document read.View the accepted manuscript
- Kerr NL. HARKing: hypothesizing after the results are known. Personality and Social Psychology Review. 1998;2(3):196–217. doi:10.1207/s15327957pspr0203_4 the original is behind a publisher restriction and was not read. The definition quoted here is as reproduced by Mohseni A, “HARKing: from misdiagnosis to misprescription”, PhilSci-Archive preprint, read 20 October 2026.View the preprint that quotes it
- Murphy KR, Aguinis H. HARKing: how badly can cherry-picking and question trolling produce bias in published results? Journal of Business and Psychology. 2019;34(1):1–17. doi:10.1007/s10869-017-9524-7 read 20 October 2026 from an author-hosted copy.View the full text
- Munafò MR, Nosek BA, Bishop DVM, Button KS, Chambers CD, Percie du Sert N, et al. A manifesto for reproducible science. Nature Human Behaviour. 2017;1:0021. doi:10.1038/s41562-016-0021 read 20 October 2026 from an institutional repository copy.View the full text
- Amrhein V, Greenland S, McShane B. Retire statistical significance. Nature. 2019;567(7748):305–307. doi:10.1038/d41586-019-00857-9 the repository record and abstract were read 20 October 2026; the full comment was not reachable, and only the abstract is relied on here.View the record
How to cite this article
Pick your referencing style and copy it. Your university or target journal may vary the punctuation — check its guide if it has one.
This article is written to be learned from. Cite it if you are referring to what it says; if you are using the evidence behind it, cite the sources listed above instead.
Work through these before you analyse.
[ ] Null hypothesis stated in full, about the population parameter
[ ] Alternative hypothesis stated, and its direction decided
[ ] Two-sided test used, or a one-sided test justified in advance
[ ] Alpha fixed in the protocol and not revised afterwards
[ ] Power calculated in advance, 0.8 or higher
[ ] Sample size derived from that power calculation
[ ] Smallest effect size of interest defined, if equivalence matters
[ ] Equivalence or non-inferiority margin set before data collection
[ ] Analysis plan preregistered
[ ] Number of tests performed disclosed
[ ] Exploratory analyses labelled as exploratory
[ ] Exact p-value reported, not just "significant" or "ns"
[ ] Effect size reported with a confidence interval
[ ] Non-significant results phrased as no evidence of a difference
We help you state testable hypotheses, calculate power and sample size before data collection, choose between significance and equivalence testing, and report results in language a reviewer will not have to correct.